Signal Noise Reduction in High-Frequency Deployment Environments
AI agents overwhelm code review systems built for human-speed development.
Experienced developers working in their own repositories took 19 percent longer to finish tasks with AI tools, but they believed they had finished about 20 percent faster. That gap, documented in a randomized controlled trial run by METR, is the clearest evidence available that something has gone wrong with how engineering teams read their own signals under agentic workloads. Every system built to catch bad code, from code review to CI to the merge queue, was sized for the pace at which a human types, not the pace at which an agent produces diffs.
Agentic Deployment Volume and Signal Filtering in Human-Paced Pipelines
Agents can now write code at almost no cost. What they have not done is change what happens after the code is written. A pull request generated by an agent still has to pass through the same review pipeline, the same CI fleet, and the same merge queue that a human-authored pull request passed through five years ago, and those systems were never designed with agent-scale throughput in mind. The constraint that used to sit at the authoring stage has simply relocated downstream into review and integration, so teams with high AI adoption are merging far more pull requests than they used to while their delivery metrics barely move.
That relocation would be tolerable if the quality of what's being merged held steady, but it has not. Research tracking more than 211 million changed lines of code authored between 2020 and 2024 found that the share of changes associated with refactoring fell sharply, while duplicated code blocks multiplied eightfold over the same period. Output volume grew; the signals that typically indicate disciplined, maintainable change deteriorated at the same time. Layered onto that is overconfidence that one trial found systematic: developers were not randomly wrong about their own productivity, they were wrong in one direction, consistently. The miscalibration is a property of the tooling and the workflow, not a coincidence of sampling.
None of this means agents produce worse code than humans do on some abstract quality scale. It means the volume of change agents enable breaks assumptions baked into pipelines that were tuned for a much lower arrival rate. A higher volume of changes produces more CI runs. More CI runs surface more flaky results. More flaky results trigger more retries. If a handful of engineers push code by hand, a mechanism like this is mildly wasteful, but run it at agent frequency, many times an hour across many agents at once, and it becomes structurally damaging.
The Merge Queue as Primary Amplifier of Noise Under Agent Load
The merge queue is where this mismatch does the most visible damage, because queuing behavior does not degrade gradually as load increases. It degrades in a curve that stays flat for a while and then rises sharply as arrivals approach the system's service capacity. If merge-group CI takes 30 minutes from trigger to result, a strictly ordered queue lands at most 48 pull requests in a day. Introduce agents into that pipeline and the arrival rate can triple overnight, while the CI service rate, the actual speed at which checks run, stays exactly where it was. The queue that added a few minutes of wait time last quarter adds hours this quarter, and nothing about the CI infrastructure itself got any slower. The capacity simply ran out.
Atlassian's own published case shows what this looks like at scale before a fix is applied. With more than 800 developers and over 300 merges a day, semantic merge failures, changes that pass review individually but break when combined, accounted for a significant share of all CI failures and were driving multiple incidents a week. The fix was architectural: ordering changes so that conflicts surface before merge.
RunPod's 2026 experience shows the mirror image of that lesson. RunPod fixed account isolation and enabled genuine pool-mode parallelization, not adding a single machine, and that cut merge-queue CI time by more than half. Teams repeatedly misread a noisy signal as a resource problem when the actual source of the noise was a structural assumption buried in the test architecture itself.
Flaky tests compound the damage in a way that is specific to agents. An agent instructed simply to get a pull request merged will re-queue the same change repeatedly until it lands, turning a retry pattern that was mildly wasteful at human frequency into something close to a denial-of-service attack on the merge queue at agent frequency.
Context Rot as an Agent-Specific Failure Mode
Pipeline noise is something agents produce and something agents consume, and the consumption side has its own failure mode. Context rot describes what happens when the information an agent actually needs to act correctly, repo maps, architecture decision records, the state of failing tests, API contracts, gets displaced inside the agent's context window by irrelevant history accumulated from a noisy environment. The window has a fixed size. Every stale log, every redundant status update, and every retry artifact that gets carried forward competes for space with the information that would have kept the agent on track.
An arXiv preprint examining cooperation among LLM agents in game-theoretic settings found something counterintuitive: longer visible history often degraded cooperation rather than improving it. More memory is not automatically more useful. In many of the settings tested, it made coordination worse, so expanded recall looks like a failure mode in multi-agent settings, not an improvement.
Stripe's study of how agents actually consume SDK and CLI documentation sharpens this point considerably. An agent could in principle read passive documentation, but it mostly ignored it. What reliably changed agent behavior were hard steering signals placed directly in the loaded context: skill files, error messages, and CLI prompts that appeared at the moment the agent needed them. The lesson runs against the instinct to simply write more documentation or log more detail. Signal placement did more work than signal volume. One well-placed error message changed outcomes more than pages of reference material the agent never meaningfully used.
This has a direct bearing on how agent orchestration is built, because an agent's accumulated skill set is itself a source of context rot. Skills retained from earlier tasks but never pruned sit in the same context window as the skills relevant to the task at hand, and they displace exactly the signal the agent needs in the moment. The noise, in that case, is internally generated, built up over time by an agent configuration nobody went back to clean.
Multi-Agent Orchestration and Second-Order Noise
Complex engineering tasks have outgrown what a single agent's context window can reasonably hold. That is why the dominant deployment pattern now pairs one orchestrator agent with several specialized sub-agents working underneath it. Gartner forecasts that task-specific agents will be integrated into 40 percent of enterprise applications by the end of 2026, up from less than 5 percent the year before. The orchestrator-plus-sub-agents pattern is now the operating norm for agentic software delivery.
That architecture changes what noise does once it enters the system. Context management at the level of one agent cannot catch this, because the damage happens at the coordination layer, between agents, not inside any single agent's reasoning.
The most reliable way to trace where that second-order noise entered the system is the session record: a structured log capturing user input, model response, tool call, tool result, file change, error, retry, approval, and checkpoint, in order. That record is the honest audit trail of what actually happened. The audit surface and the operating context solve different problems, and conflating them degrades both.
The resolution researchers describe as "prompt as workspace, session as ledger" keeps those two functions separate on purpose. The agent works from a deliberately curated workspace, holding only what's relevant to the task immediately in front of it. The session, meanwhile, functions as a durable event log maintained for post-hoc analysis, available when something needs to be reconstructed, but never fed wholesale back into the agent's active reasoning.
Predictive PR prioritization offers a partial answer to the noise entering the orchestration layer from the queue itself. Rather than processing pull requests strictly in arrival order, this approach uses historical build data and PR metadata to estimate the likelihood that a given change will build successfully, then routes high-confidence changes first. Predictive prioritization reduces one kind of noise while introducing a smaller, different kind, so teams adopting it need visibility into what the model is deciding.
Eliminating Pre-Merge CI: A Different Problem Than Signal Filtering
A serious position within the practitioner community holds that pre-merge CI itself is the wrong unit of work for agent-driven velocity, and that merge queues should replace traditional CI rather than sit alongside it. Neither condition holds universally anymore. The argument deserves to be taken on its own terms rather than dismissed: if a CI suite is mostly generating flake rather than catching genuine defects, removing it does reduce the noise entering the pipeline.
It also removes signal at the same time. A CI run that catches one real regression for every nine flaky failures still catches that one regression, so if you cut the whole mechanism out, you solve a throughput problem but quietly reopen a correctness problem, unless you build something equally rigorous to replace it.
DORA's research complicates any simple "just move faster" framing. The 2024 edition found that higher AI adoption was associated with reduced delivery performance and greater instability at the team level. A team with weak feedback loops does not get steadier by moving faster. It gets less steady, faster.
TDD-style agent patterns point toward what a workable replacement actually looks like. Whether a team keeps CI, replaces it, or runs some hybrid of the two turns out to matter less than a separate question: what production signal is actually being fed back into the agent's workflow. Teams without a structured feedback loop from production, exceptions, query degradation, deploy failures reaching the agent as usable input, will see instability grow with throughput regardless of which pre-merge architecture they choose.
Feeding Production Signals Directly Into Agent Workflows
The human-era model for handling production signal runs through a dashboard: an alert fires, a human notices it, the human decides whether it merits action, the human opens a ticket if it does. Every step in that chain adds latency, and that latency is incompatible with the frequency at which agents now ship change. A signal that sits in a dashboard for an hour before a human looks at it is a signal that arrives an hour too late for an agent working at agentic cadence.
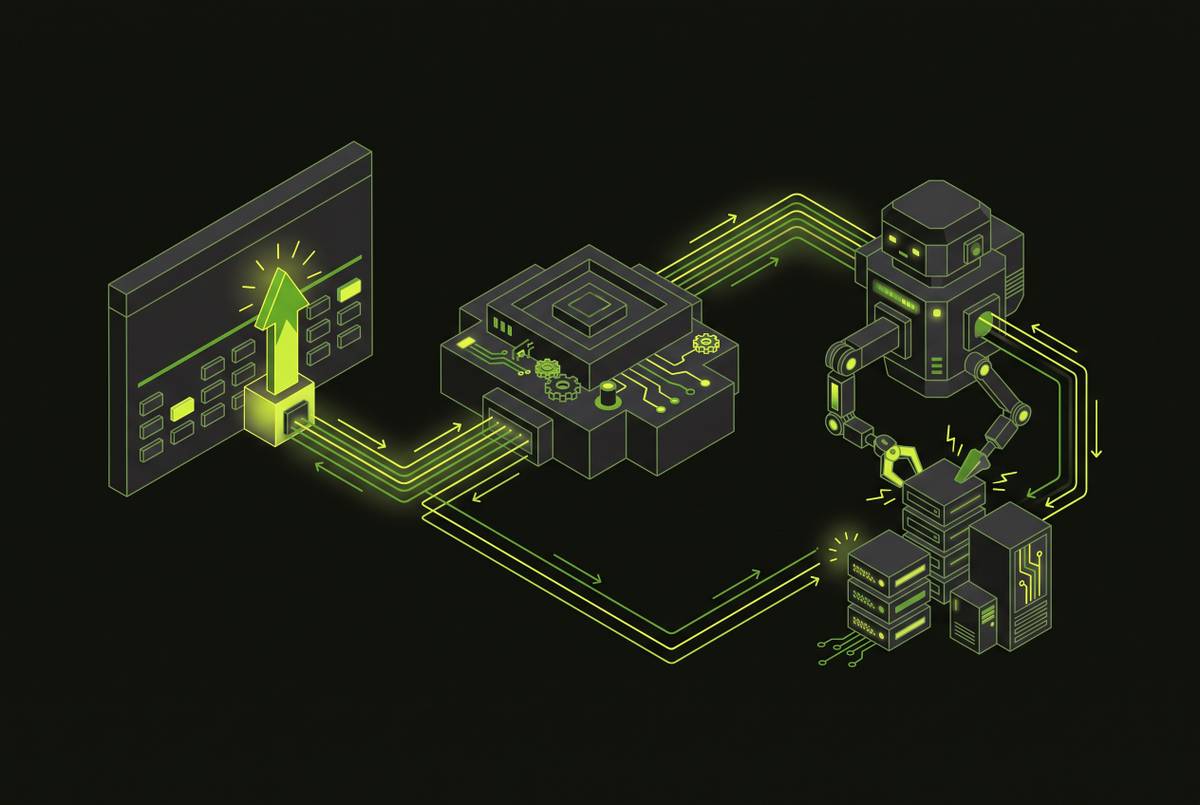
The alternative routes the same signal directly into the pipeline as structured input. A failing test pattern, a spike in exceptions, a regression in query performance becomes input delivered straight to the agent responsible for the affected code, rather than a notification waiting for a human who may or may not be watching at that moment. That requires the signal itself to be structured and actionable rather than merely voluminous. A raw dump of exception logs is not a signal an agent can act on. A classified, attributed, reproducible failure, tied to a specific piece of code and handed to the agent that owns it, is.
The same deterministic principle that makes test-first patterns effective pre-merge applies here. Routing production signal directly into agent workflows is the mechanism that breaks that coupling, rather than a convenience layered on top of it.
Composable Infrastructure for Signal Filtering at Agentic Scale
No single platform can be tuned simultaneously for a human review cadence and an agent's throughput, because the two have fundamentally different load profiles, retry behaviors, and tolerance for latency. That's why signal filtering at agentic scale is ultimately an infrastructure composition problem rather than a tooling selection problem, and why teams that try to solve it by buying one all-in-one platform tend to run into a wall.
The pattern taking hold in 2026 is composable: assembling an internal developer platform out of best-of-breed components joined by thin integration layers, rather than depending on a single vendor to cover every function at once. Platform Engineering 2.0 describes this as delivering capability through modular, independently deployable, API-first building blocks, each of which can be swapped out without forcing a cascade of changes through everything connected to it. You cannot simply reconfigure a monolithic platform tuned for a human review cadence for agent throughput, because that breaks assumptions the rest of the stack depends on. It has to be replaced wholesale. The replacement cost of monolithic platforms has gotten so high as agent adoption accelerates.
The composable reference stack taking shape in 2026 starts with a developer portal, commonly built on Backstage, Port, or Cortex, as the layer through which engineers and agents alike discover services, ownership, and the state of the system. Built around that core, teams are assembling CI orchestration, merge-queue management, and production-signal routing as separate, interchangeable components rather than features bundled into one closed system. What matters is the architectural principle: a signal filtering problem produced by agentic scale needs an infrastructure answer built to flex at that same scale, assembled from parts that can each be replaced the moment they stop fitting, rather than a single platform asked to do a job it was never sized for.